

Hey! I'm Sam, and I work as a physical design engineer at IBM. Most of what's here is things I got curious about and explored on my own, plus some projects from school. Lately that's mostly been machine learning applied to the chip flow, and using open-source tools like OpenROAD to experiment.
Always happy to talk chips, physical design, or open-source silicon. You can find me on LinkedIn.
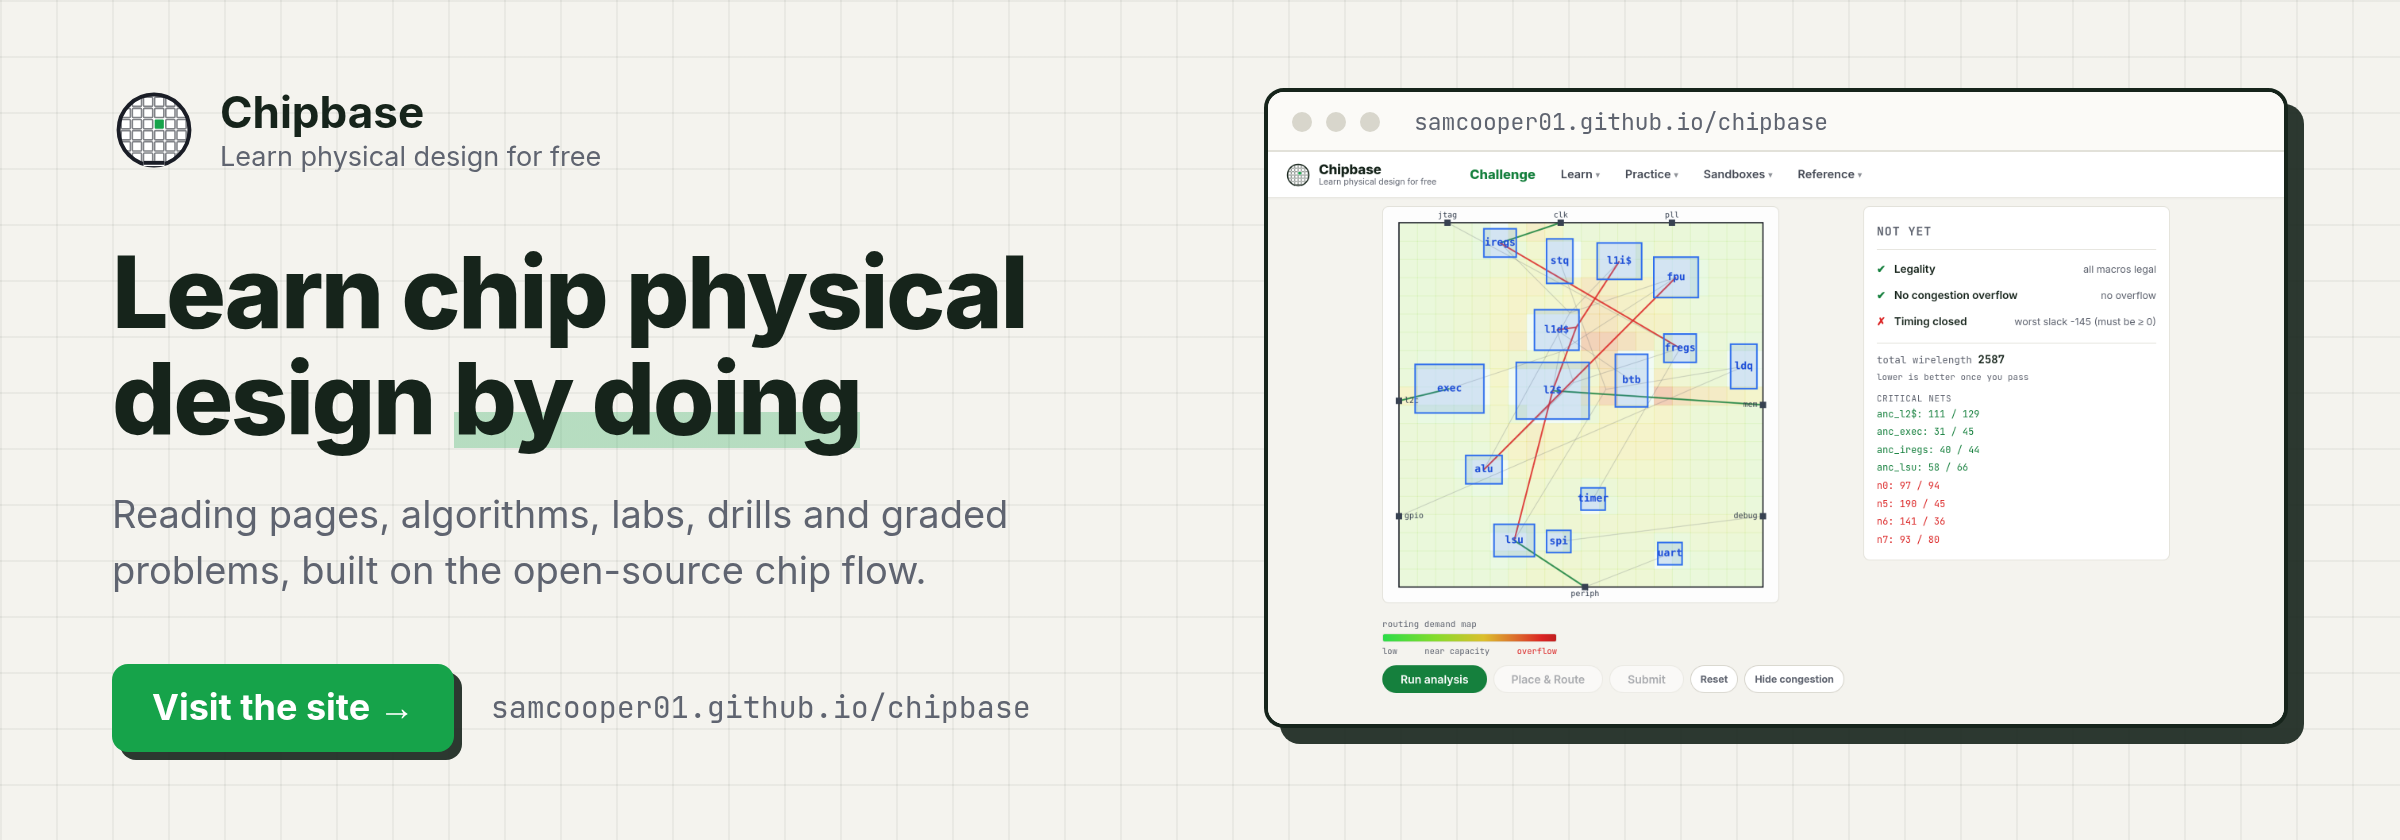
A free site for learning physical design, built because the material I wanted when I was starting out is scattered across papers, course notes and tool manuals. It has reading pages on every stage of the flow, pages on the algorithms underneath them, interactive labs, drills, and fifteen problems graded in the browser. Live here.
systolic-array-ai-accelerator-harness The evaluation harness for the first design competition on Chipbase. Entrants take Gemmini, an open AI accelerator built around a 16 by 16 systolic array, from Verilog to a finished layout on the ASAP7 7nm predictive process using only open tools, and anything that clears the gates is scored on clock period, area and power against a reference flow. That reference is in here too: around 200,000 cells, macros placed by hand, one clock tree reaching about 35,000 registers, routed clean on nine metal layers.
rl-macro-placer A reimplementation of Google's reinforcement learning macro placer from the 2021 Nature paper: an agent places the hard macros one at a time, a force-directed pass settles the standard cells around them, and a wirelength, congestion and density proxy scores the result. The point was to build the whole method at laptop scale and measure honestly what carries over and what does not.
Open-SRAM-Compiler-ASAP7nmPDK An SRAM compiler for the ASAP7 7nm predictive process. Three parameters in, a verified memory macro out: full-custom layout, an abstract for place and route, a timing library and a behavioral model. The verification stack runs eleven automated tests, from 97 transcribed design rules to switch-level simulation of the extracted netlist. Largest built and verified so far is 8 kilobytes.
I wanted to see if the default recipe for open-source logic synthesis could be improved on. Usually it can: up to 5.8% less area at the same clock speed, on 6 of 9 designs. I searched for per-design recipes with reinforcement learning, a graph neural network and a genetic algorithm, grading each one on a real layout. Write-up here.
Std-Cell-Layout-Gen A generator that turns a transistor netlist into a manufacturable standard cell layout with nobody drawing anything by hand. Each cell gets a short recipe of knobs while the process rules and library architecture stay shared, so you can change a technology parameter, rerun, and get a whole co-legal library back. 319 of the 437 cells in the SKY130 high-density library build clean so far.
GEMM_CORE A 4-bit floating point matrix multiply engine, taken from Verilog to a finished layout on SkyWater's open 130nm process. The processing element and vector unit were hardened as separate macros and the top built from 64 of them, so timing closed hierarchically: 1.63 mm² at 65% utilization, clean across three corners. A five-person project for ECE 755, VLSI Design; my part was the physical implementation and the floating-point arithmetic.
Multi-Layer-Perceptron An end-to-end full-custom design: a multi-layer perceptron built from hand-drawn cells rather than a standard cell library. Every cell has a schematic, a transistor-level layout, an extracted parasitic netlist and a post-layout simulation, which is a good way to find out how much of a cell's delay is really wire.
128bitFeistelCipher-ASIC A block cipher I took from a C golden model through synthesis, static timing and power analysis, in two variants to see what reorganizing the key logic bought. Done over a weekend.
ECE554-Capstone-Project Real-time object detection and laser targeting on a Cyclone V board: a camera feeding frame-differencing logic built in hardware, a servo-driven laser that tracks whatever it finds, and a video overlay so you can watch it work. Five of us built it, and it won best capstone in the class.
Matrix-Multiplication-Module A matrix-vector multiply unit: eight multiply-accumulate lanes behind input queues, pulling operands over an Avalon memory-mapped interface, constrained to 200 MHz and checked in the timing analyzer.
ECE552-5-Stage-Pipelined-Processor A five-stage pipelined processor in Verilog, with forwarding, branch prediction and its own memory system: caches built twice, once direct-mapped and once set-associative, so the two could be compared.